More duplicates found than exact-match rules
Person and organization records flagged for potential reconciliation
Per full run, compared with about $600 on pay-per-use services
The school’s executive education and online learning divisions manage prospects, students, and organizations in Salesforce. Records arrive through many intake forms and are enriched with third-party firmographic data from sources like Dun & Bradstreet.
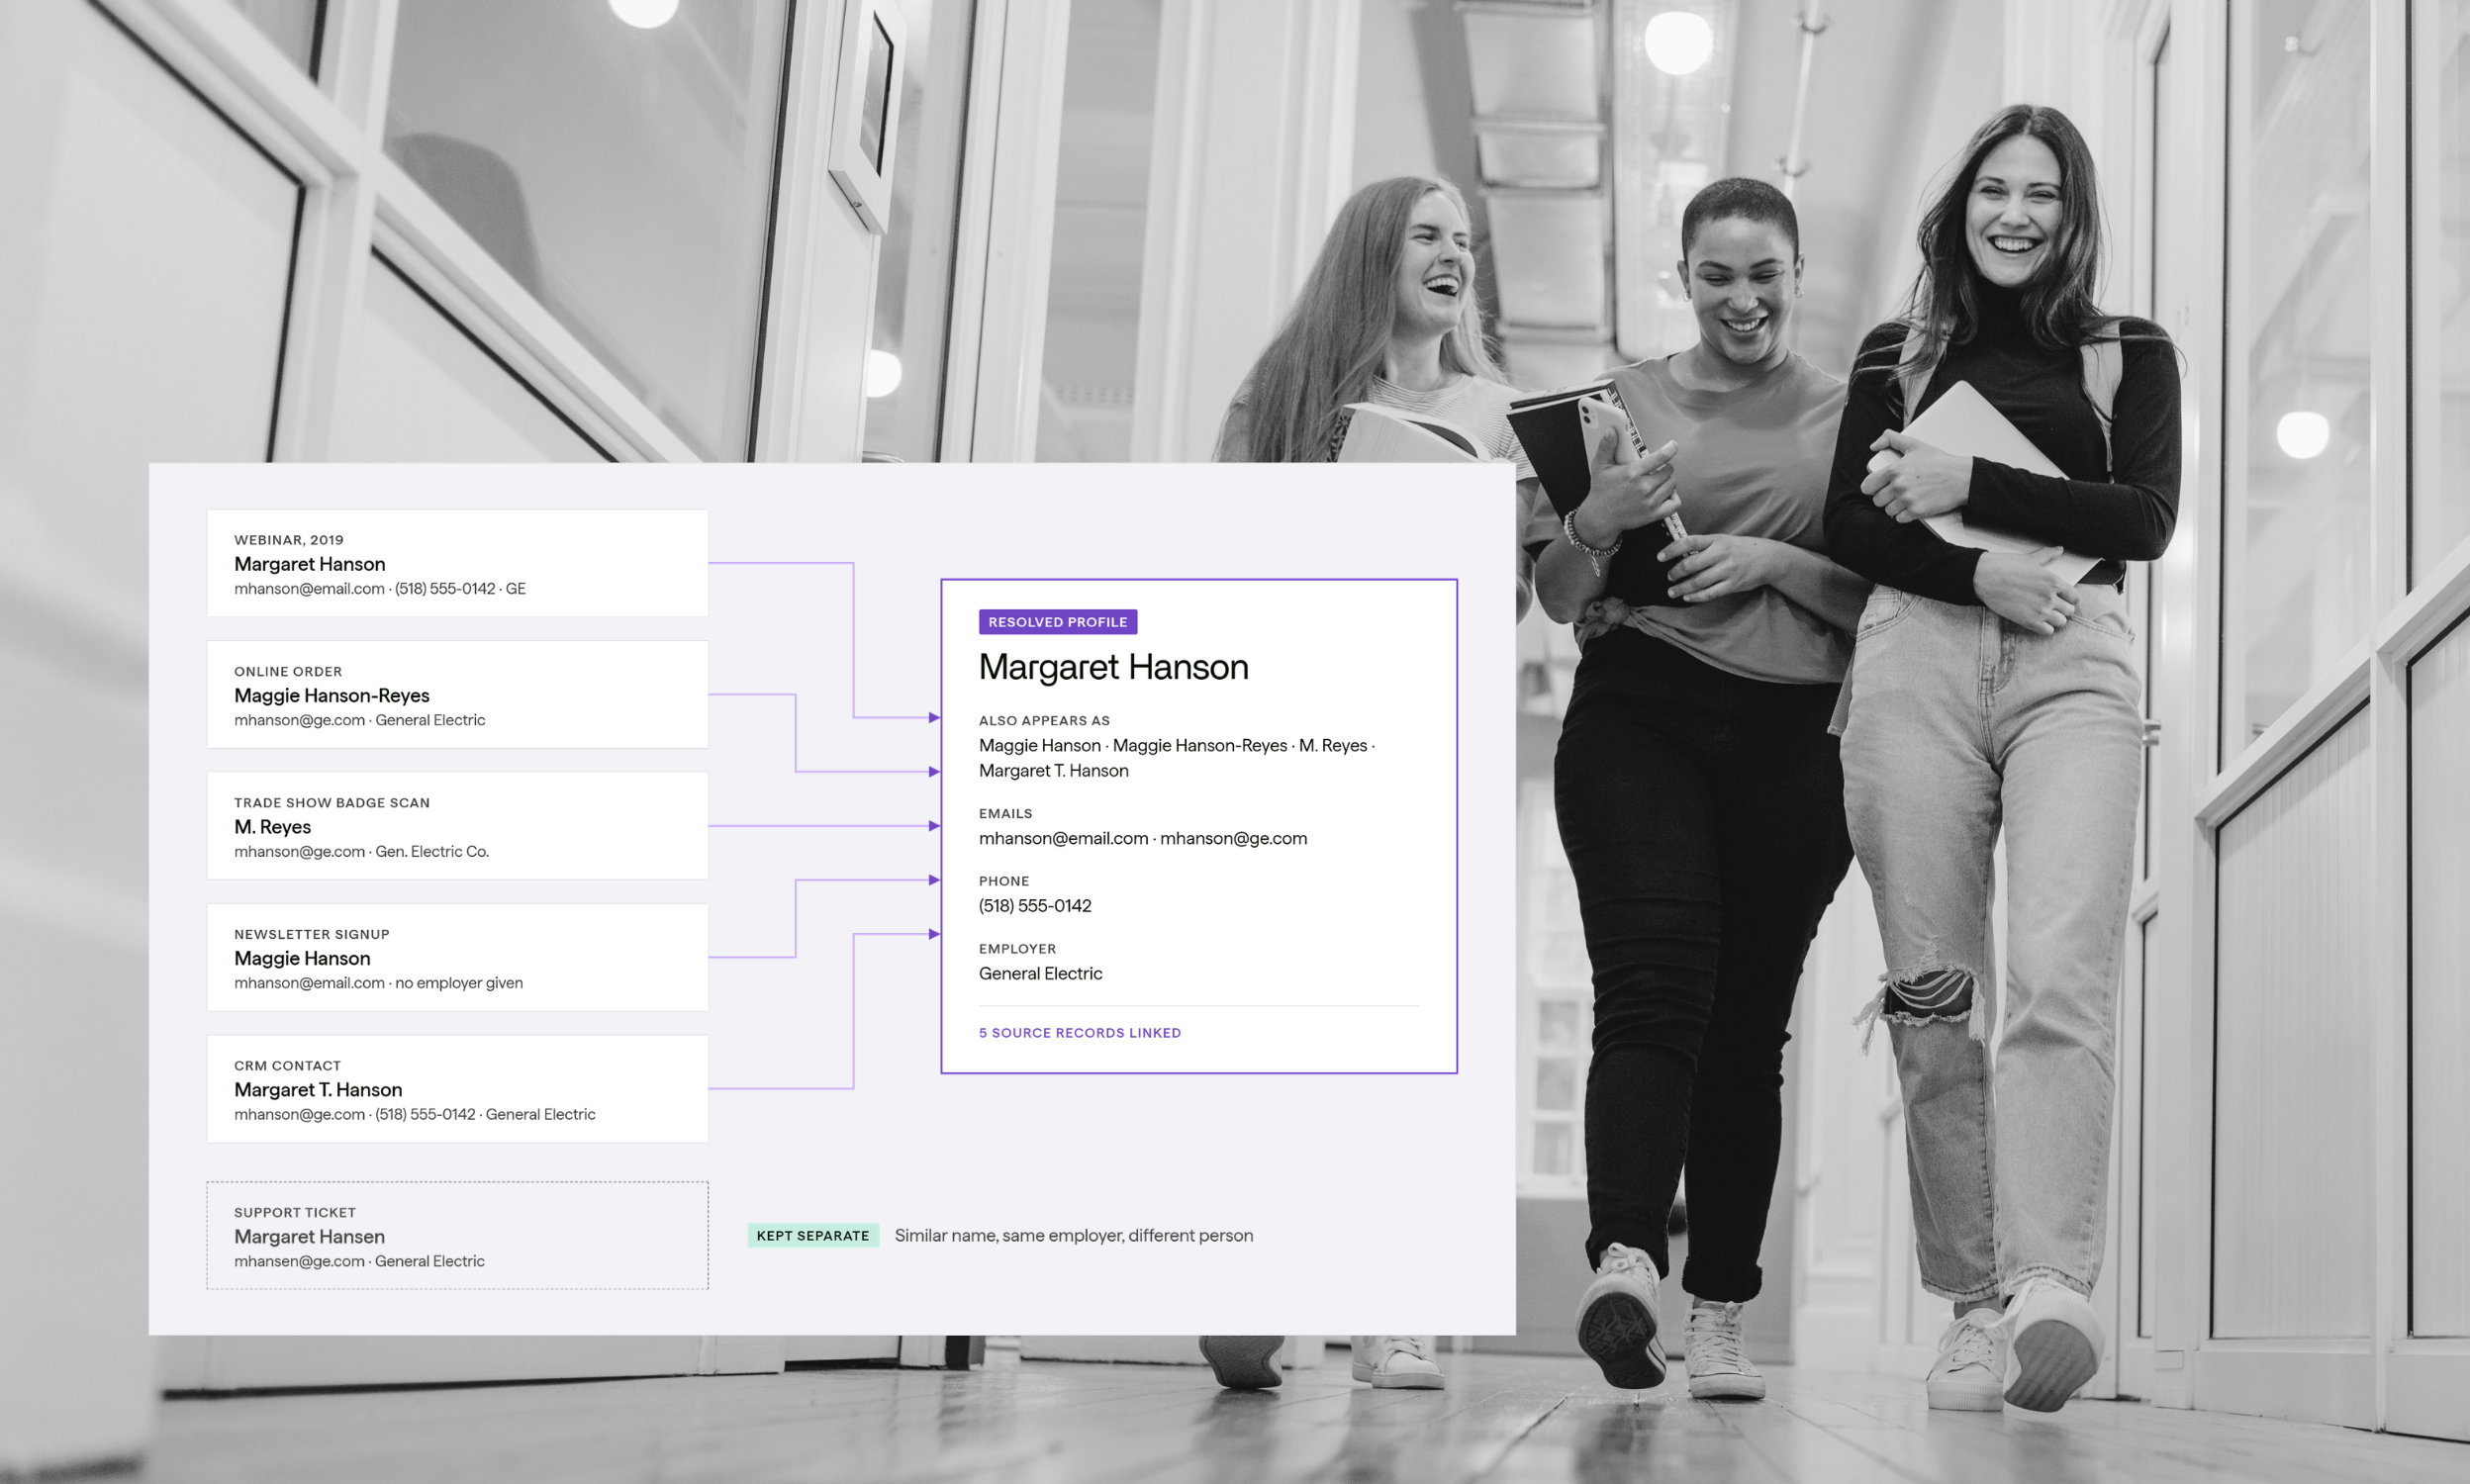
Over time, inconsistent user-entered data and attribute drift built up duplicate and fragmented records: a name typed two ways, a personal email in place of a work one, the same organization listed three different ways. Standard dedupe rules caught exact matches and missed the rest, and manual review couldn’t keep pace with daily incoming records.
Without a trusted view of each person and organization, the school couldn’t confidently build the analytics, personalization, and AI initiatives on its roadmap. It needed identity resolution that ran inside its existing Snowflake account, scaled to millions of records, and could show its work.
OneSix built a hybrid identity resolution pipeline that runs end to end in the school’s Snowflake account on Snowpark Container Services. Data never leaves the platform.
Vendor platforms are the usual alternative. Master data management and entity resolution tools typically cost from about $59,000 to more than $200,000 a year in licensing, or around $600 per run on pay-per-use services at this data volume, before implementation and staffing.
Building inside Snowflake ties cost to compute instead. A full run costs less than a dollar, every match shows the evidence behind it, and the outputs are ordinary Snowflake tables with no proprietary system to migrate out of later.
Exact-match rules handle the high-confidence links. Machine learning models score every other candidate pair, catching the typos, nicknames, reversed names, and near-misses that rules alone overlook. A full run takes about 20 minutes.
The pipeline finds up to 2.5 times as many true duplicates as exact-match rules, even on data Salesforce had already deduplicated, flagging roughly 120,000 person records and 44,000 organization records for potential reconciliation. Every run benchmarks its results against human-reviewed and AI-evaluated samples. When a match had more than a name to go on, human reviewers confirmed 91% of them.
Every resolved identity traces back to its source record, model, and code version. Routine operations run as Cortex Code skills, and the pipeline can extend to other divisions and data sources with no rebuild, laying the groundwork for a golden record and Salesforce write-back.
Read the full story on build vs. buy, where AI fits, and lessons from resolving millions of records.
More to explore
OneSix implemented a data warehouse solution for a commercial printing client, transforming IoT sensor data into real-time, actionable insights that enhanced operational visibility and reduced downtime.

OneSix deployed a Microsoft Copilot Agent for marketing that saves four to six hours per proposal and established the firm's first sanctioned AI use case.

OneSix built an end-to-end data platform that unifies patient, prescriber, and payer data across every touchpoint in the therapy journey.