Same Person, Five Records: What Actually Works in Identity Resolution
Build vs. buy, where AI fits, and lessons from resolving millions of records
Written by :
Michael Clark, Senior ML Scientist
October 16, 2026
Every organization that has collected customer data for long enough has the same problem. One person shows up as "Margaret Hanson" from a 2019 webinar, "Maggie Hanson-Reyes" from an online order, and "M. Reyes" from a trade show badge scan. Her employer appears as "GE" in one record and "General Electric" in another, while "GE HealthCare," despite the name, is now a separate company. Each record looks reasonable on its own. Together, they quietly break reporting, marketing, and every AI initiative built on top of them.
We see this problem regularly in the real world, whether the data sits in a CRM, a marketing platform, or a data warehouse. Our approach is to resolve identities inside the data platform an organization already has, using transparent, explainable matching rather than a black box.
In a recent engagement, we applied this approach to separate sets of person and organization records in Snowflake. Here are the results after the first full run.
The results at a glance
2.4 million person and organization records resolved inside Snowflake, in about 20 minutes per run from initial data to scored matches
2.5x as many true duplicates found as exact-match rules alone
85% raw agreement with human-reviewed cases
91% of matches confirmed correct by human reviewers when more than a name was available to compare
Roughly 120,000 person records and 44,000 organization records potentially reconciled
This post covers what identity resolution is, how to decide between a vendor platform and a custom build, where AI genuinely helped (and where it didn't), and the lessons we'd pass on to anyone starting this work.
What is identity resolution?
Identity resolution answers a simple question: which of these records refer to the same real-world person or organization? It has two parts.
Matching decides whether two records describe the same entity.
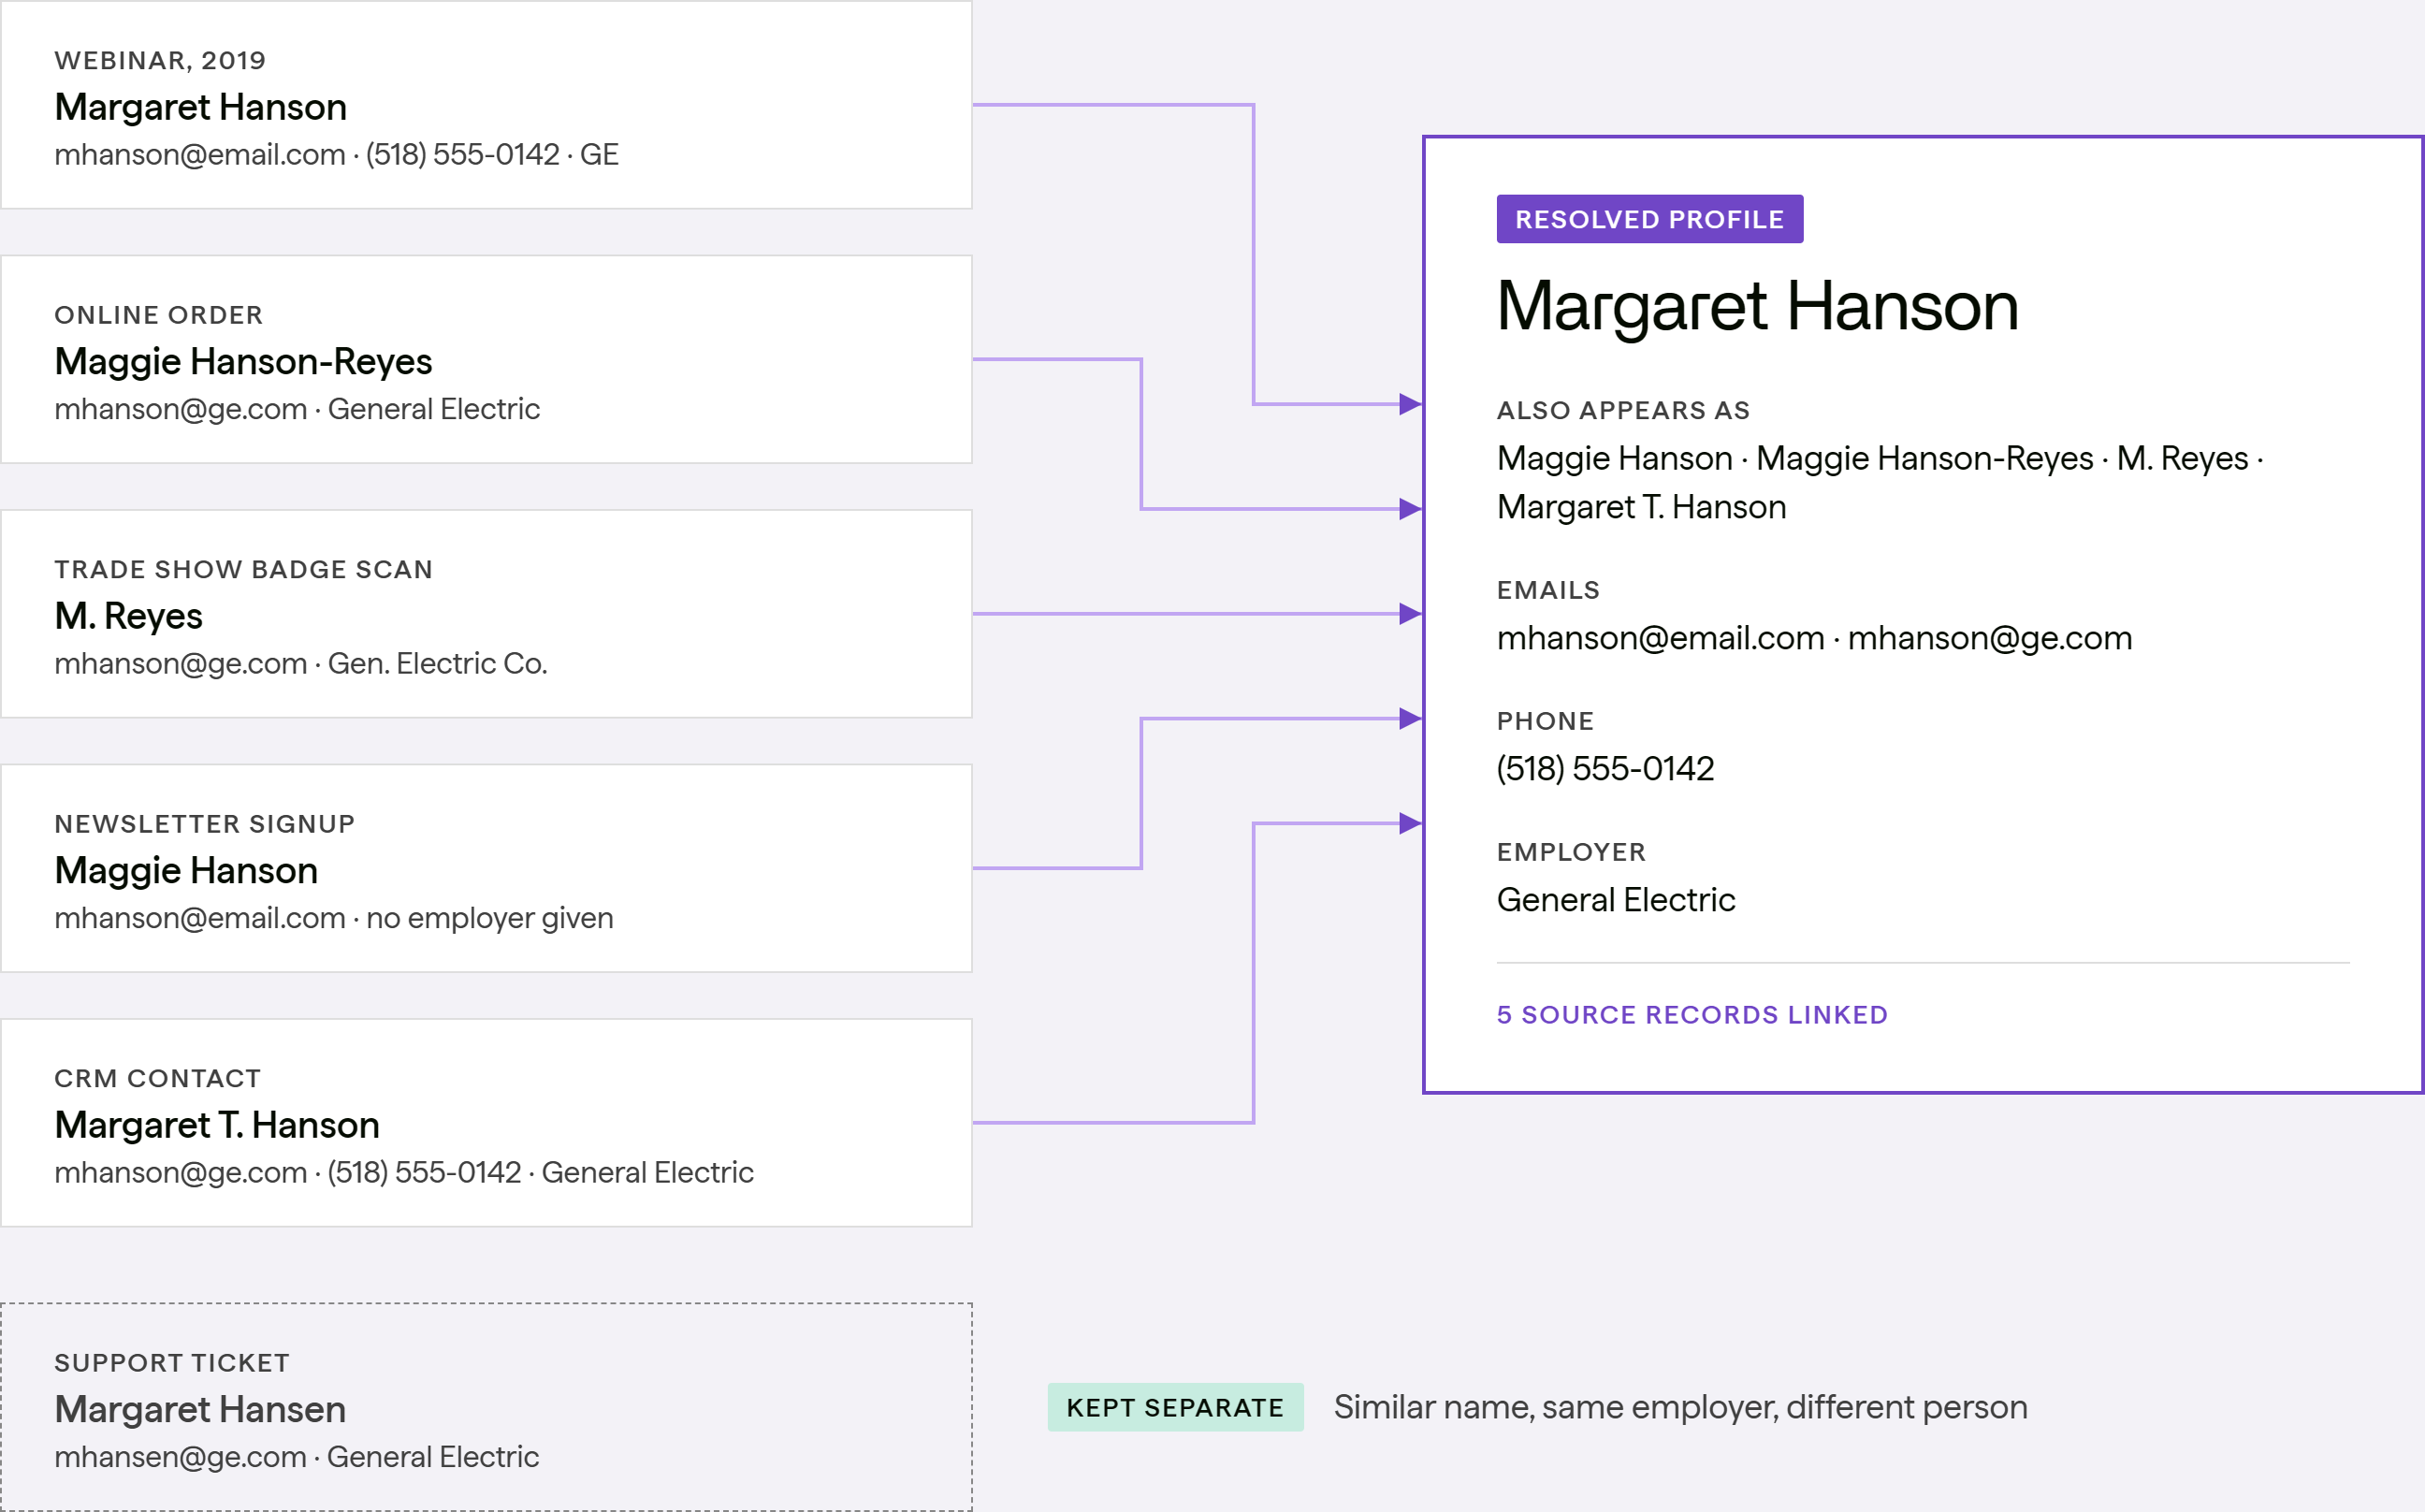
Resolving groups all the records for one entity together, so "Margaret Hanson," "Maggie Hanson-Reyes," and "M. Reyes" become one person with three source records.
Five records, one person
Matching decides which records describe the same person. Resolving groups them into one profile, while keeping look-alikes apart.
Illustrative example. Names and contact details are fictional.
It sounds straightforward until you look at real data. In practice, we routinely see:
A single placeholder email address can sit on tens or even hundreds of thousands of records. Treated as real, it potentially creates many useless comparisons to evaluate.
"Clark" and "Clarke" are essentially identical to a simple similarity score.1 As are "Columbus" and "Columbia".
"IBM" and "International Business Machines" share no words at all, while bank names like "First National Bank of X" may overlap considerably while being different banks.
Two people at the same company share an employer, a phone number, and sometimes a mailing address. That makes them look alike, even though they are different people.
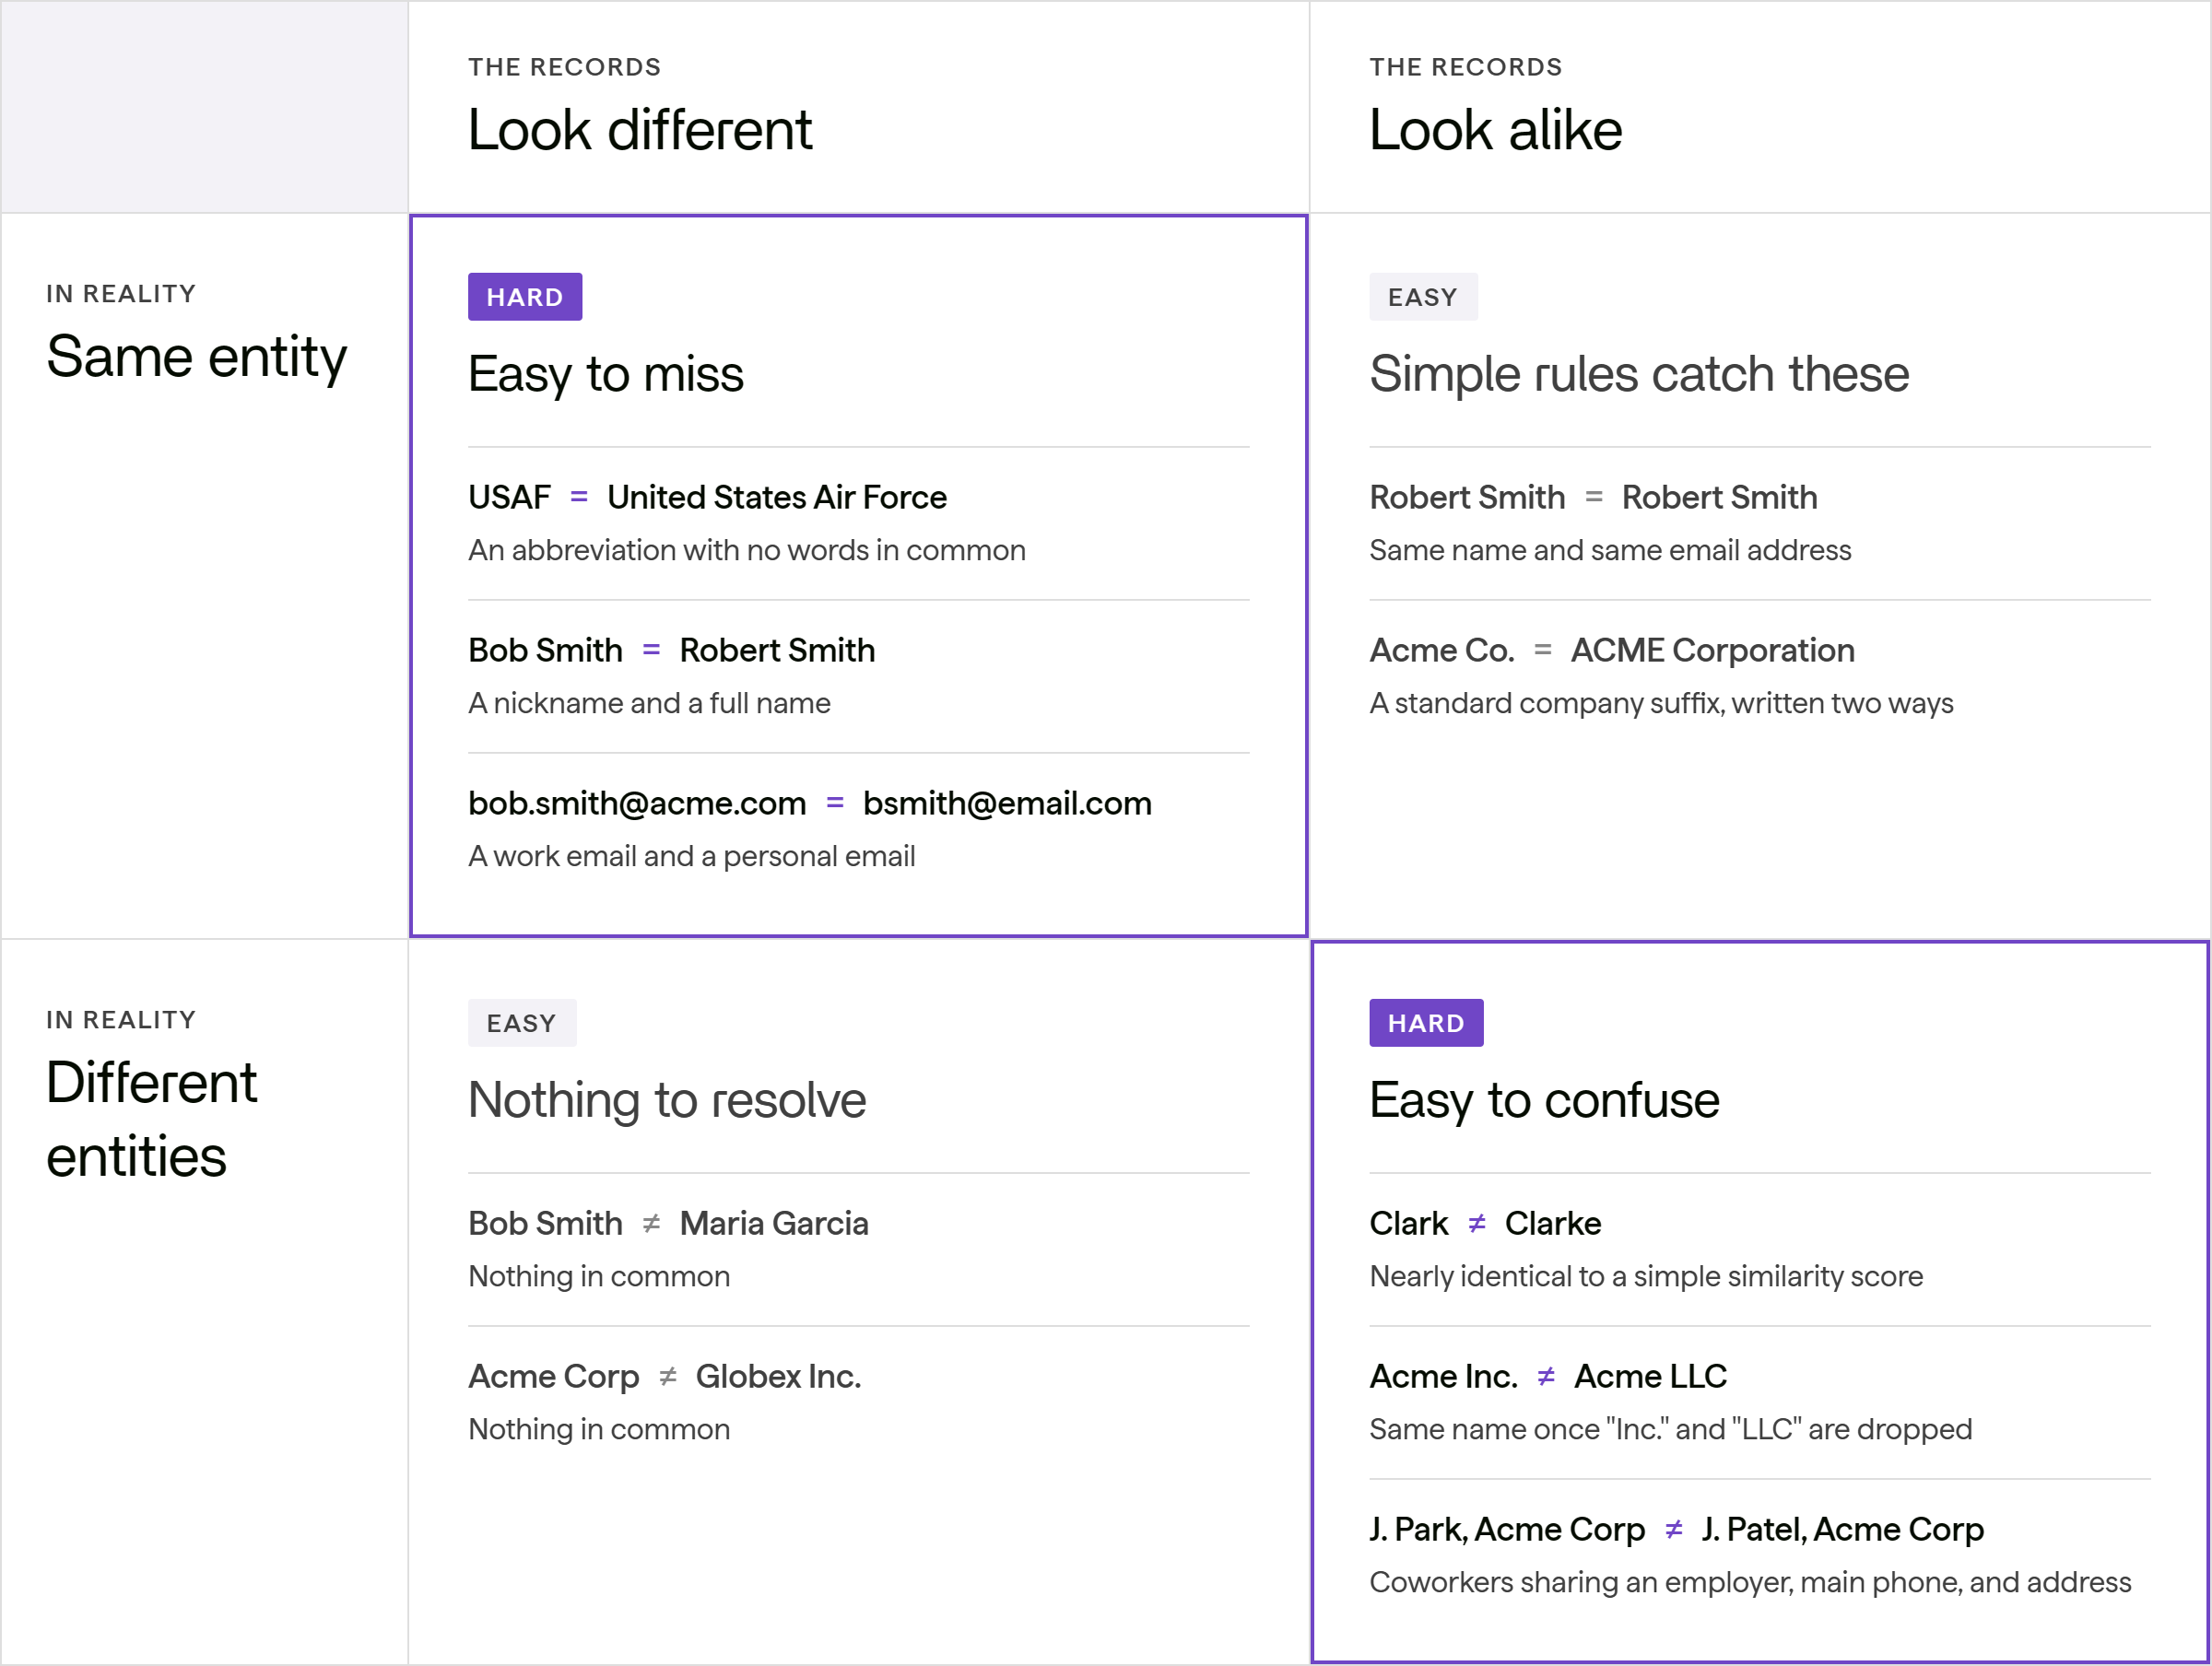
The hard cases are the ones that fool the eye
Simple rules handle the easy cases. The hard part is matching records that look different and keeping apart records that look the same.
Illustrative examples of patterns found in real customer data.
Good identity resolution handles all of this at scale, consistently, and in a way people can trust.
Why it matters now
Duplicate records have always caused headaches: the same person receiving three copies of a brochure, inflated customer counts, and an incomplete picture of an organization's relationship with you.
AI raises the stakes. Organizations increasingly put AI on top of their data: assistants that answer questions in plain English, models that predict who is likely to enroll or churn, and tools that personalize outreach. All of them assume one record means one person. Ask an assistant how many events Margaret Hanson has attended, and if she's split across three records, it will undercount and answer with full confidence. A forecasting model sees three people with partial histories instead of one with a full one. Resolved identities are part of the trusted data foundation these tools need to get the right answer.
The big question: buy or build?
There are mature commercial options for this problem. Master data management (MDM) platforms and dedicated entity resolution products from vendors like Informatica, Reltio, Tamr, Profisee, and Senzing are capable tools, and Salesforce and other CRMs offer their own duplicate management features.
The real question isn't whether these tools work. It's how much of a platform you actually need, how much work you still have to put in, and what you're willing to trade for it.
The case for a vendor platform
A vendor platform makes the most sense when identity resolution is one part of a broader master data program. These platforms typically bundle:
Stewardship tools, so business users can review and approve matches in a friendly interface
Golden records and survivorship, deciding which phone number or address "wins" when records disagree
Real-time matching, catching duplicates the moment a record is created
CRM integration, writing merged records back into systems like Salesforce
Vendor support, with a team to call when something breaks
Organizations often do need several of these, but each one depends on the core matching being done well first.
What do vendor platforms cost?
Few vendors publish clear pricing totals, but the public figures that do exist give a sense of scale. Pricing generally follows one of two models.
Pay per run. Cloud services like AWS Entity Resolution charge for every record processed, every time matching runs. At published list prices, AWS Entity Resolution's machine-learning matching, which reprocesses the full dataset every time, would cost roughly $600 per run for a database the size of our client's (about 2.4 million records).2 Salesforce Data 360 offers identity resolution on a similar pay-per-use basis, and identity resolution is one of its more costly features.3
Annual subscription. Full MDM and entity resolution platforms are typically priced by the number of records under management, often starting in the high five or six figures per year. Senzing publishes about $59,000 per year for up to 10 million records.4 Informatica's AWS Marketplace listing prices a 12-month cloud data management subscription at about $132,000,5 and industry estimates put enterprise Informatica MDM at $200,000 or more per year.6 Reltio's AWS Marketplace listings work out to about $187,000 per year,7 and buyer-reported Reltio contracts are higher still.8 Tamr, Profisee, and others don't publish prices at all.9
License fees are only part of the picture. Even vendor solutions require ongoing implementation and staffing on the part of the client, and that cost can vary widely depending on which tool is chosen and the complexity of the deployment. One vendor-commissioned study, for example, estimated about $370,000 to implement the platform and two full-time staff to run it afterward.10
Our approach: Resolve identities where the data lives
We build identity resolution directly inside the data platform an organization already uses. In our recent engagement, that was Snowflake, with the matching itself running in Python inside the platform. Every run follows the same five steps:
Clean. Find and remove junk values like placeholder emails and dummy IDs, and standardize names, addresses, and organizations.
Narrow. Only compare records that could plausibly match. This turns over a trillion possible pairs into a few million worth examining.
Score. A machine learning model weighs each piece of evidence and gives every pair a match probability, along with the reasons behind it.
Group. Link the matches into one profile per person or organization, while keeping look-alikes apart.
Measure. Check every run against a set of pairs already verified by human and AI review, so quality is measured, not assumed.
All of it runs automatically on a schedule. Building this way has several advantages:
The data never leaves. Matching runs inside Snowflake, governed by the access controls already in place. There's no second copy of personal data in a vendor's cloud, and no new security review for an external platform.
Cost follows compute, not record counts. A full run covering all 2.4 million records costs less than a dollar in Snowflake compute.11 Many vendor platforms price by the number of records or profiles, so costs grow with the database whether or not the matching gets harder.
Every match can be explained. Each match comes with the fields that drove it, for example "names and birthdates agreed, emails didn't." Every run is logged, so any result can be traced back to the source records and settings that produced it.
It's tuned to the actual data. The rules for placeholder values, organization names, international naming conventions, and shared employers were all built around this client's real records, not generic defaults.
No lock-in. The outputs are ordinary tables in Snowflake, keyed to the original record IDs. The matching engine is open source, and there are no proprietary golden records to migrate out of later.
You only build what you need. You don't pay for stewardship and workflow features you don't need yet.
The trade-off is real. Building it yourself has its own upfront cost: the engineering to design, build, and validate it. It also doesn't come with a stewardship interface, real-time matching, or a vendor support line. If those are needed later, they have to be built or bought.
Choosing the right approach
Custom build in your data platform
Vendor MDM / entity resolution
Where your data lives
Stays where it is
Usually copied to the vendor's platform
Upfront cost
Engineering to build and validate
Implementation and configuration services
Ongoing cost
Very inexpensive per run
Annual license, often five to six figures, or a fee per run
How cost scales
With compute used
Often with record or profile volume
Explaining a match
Every match shows its reasons
Varies; some implementations can be harder to audit
Fit to your data's quirks
Built around them
Generic logic plus configuration
Packaged extras: a review app, real-time matching, sending results back to the CRM
Can be added as needed, each at some cost
Varies by vendor; often included in MDM platforms, less so in pay-per-use services
Switching later
Plain tables, open-source engine
Migrate out of a proprietary system
A vendor platform is likely the better fit if you need a full master data program now, you want packaged features like a review app or real-time matching without building them, or you don't have a data team to own a pipeline.
A custom build is likely the better fit if your data already lives in a modern data platform, you need resolved identities for analytics and AI more than you need a new operational system, explainability and data governance matter, or your data has quirks generic tools handle poorly.
For many organizations, the answer is sequential rather than either/or: resolve identities in the data platform first, prove the value, and add MDM-style capabilities as the need becomes concrete.
Where AI fits (and where it didn't)
We considered several ways of using AI, and our own results were nuanced. It's tempting to assume the modern answer is to point a large language model at every pair of records and ask, "Same person?" Cost doesn't rule that out, but it has to be considered. After narrowing the field to plausible pairs, this client had over 6 million candidate pairs, and a broader search could easily have doubled or tripled that. At that volume, the latest frontier models would run from hundreds to a few thousand dollars per full pass, and while smaller models cost less, they are less reliable when records have little to compare or contain noisy information.12
Cost isn't the only issue. A bare yes or no is not much to work with. To supplement, you can ask the model for a confidence score and/or its reasoning, but that adds to the cost, and language models have historically been poor at producing reliable numeric ratings. Verdicts can also contradict each other within a group or change from one run to the next, and cheaper models tend to slip on the hardest cases.
While pairwise matching is the simplest use of AI in this context, it only answers the question it's asked: are these two records the same? Something else has to decide which pairs to ask about, and something else has to assemble the "yes" answers into groups. Our pipeline already does both. And whenever the inputs, the matching configuration, or the model changes, the whole set needs judging again to keep match quality high. Our matching model handles the same pairs at a much lower cost, and shows its reasoning for every match.
Where AI earned its place
AI as the answer key
The hardest part of identity resolution isn't building a matching model, it's knowing whether the result is right. There was no existing list of known duplicates to check against, and human review is time-consuming. Our reviewers also couldn't reach a firm verdict on roughly a third of person-record pairs, because the records simply didn't contain enough information.
So we used an AI model, run directly inside Snowflake, to review samples of candidate matches, the same way a person would. It agreed with human review at a rate similar to the matching model, which made it possible to measure quality on every run without scaling up manual review.
AI as the operator
Day-to-day tasks like running the pipeline, checking results, and expanding the review sample were packaged as skills for Snowflake's CoCo, its built-in AI assistant. That makes the system easier for the client's team to run without memorizing technical procedures and related aspects. Future work will likely focus on expanding this and automating more aspects of the identity resolution workflow (e.g., with the new CoCo automation capabilities).
AI as an extra signal
Embeddings, numeric fingerprints of text, can potentially catch similarity that simple string comparisons miss, and in early tests we found this to be the case. However, they're better suited to longer, richer text than to names and addresses, and comparing the vectors across millions of pairs is demanding. We built them into the pipeline so they can be switched on when the payoff justifies the compute.
Where we are now
For this setting, AI proved most valuable as a supplement to our matching model: checking quality and helping people run the system, adding signal the matcher can use, or potentially serving as the decider for less certain cases. With cheaper models or more efficient implementations, its role could easily expand further. This is already happening: in fall of 2026, OpenAI released GPT-6 Luna and Anthropic released Claude Haiku 5.5, with substantial quality gains over their predecessors.
Importantly, a new class of models built only for classification, led by TypeSafe AI's Jev, is a promising step in that direction. Instead of generating a text response, these models answer a fixed question, such as "Same person?", and return the answer along with a confidence score.13 They charge only for the text they read, so a full pass over our 6 million pairs would cost roughly $60 to $75 at list prices.14 Snowflake has already begun building these models into its platform, though as of this writing, the feature is in private preview and pricing hasn't been published.15
Lessons from the field
Junk data matters more than messy names. We expected the challenge to be nicknames and typos. A bigger issue was placeholder values like "noemail," "N/A," "test," and dummy IDs. One placeholder email alone would have generated billions of meaningless comparisons. Finding and removing these became paramount, and doing so improved everything downstream.
Watch for silent failures. At one point, an automated rule meant to remove placeholder values also caught legitimate ones, wiping out an entire field across more than a million records. Nothing errored, and the row counts looked fine. We caught it because we explicitly tracked and reported exactly how many values each rule removed, field by field. Checks like that are worth building in from day one.
Similar isn't the same. Removing "Inc." and "LLC" from company names sounds like obvious cleanup, until you find that about half the names that become identical belong to different legal entities. Two records that share an employer usually belong to two different people, even though they look alike. Good matching depends as much on knowing what not to merge as on what to merge.
A name alone may be weak evidence. When a match was supported by a second piece of information, such as an email, phone number, or ID, human reviewers confirmed 91% of person matches. When only a name was available, performance dropped, because a model can be confident based on the evidence it has, but the amount of evidence is minimal. Being clear about which matches rest on strong evidence and which need review is more useful than a single accuracy number.
Exact rules miss more than you think. Simple "same email" or "same ID" rules are reliable but limited. On an evaluation sample, our matching model found 2.5 times as many true duplicates as the exact rules while showing its reasoning for each one.
Platform setup takes real time. Permissions, roles, and security reviews in an enterprise data platform take time to get right. We built and tested the full pipeline on synthetic data in our own environment first, so the work was ready to run when access came through, and the infrastructure request was trimmed to only what was needed.
The path forward
Identity resolution isn't glamorous, but it sits underneath nearly everything an organization wants to do with its data, from accurate reporting to personalized outreach to trustworthy AI.
A few principles carry over to almost any organization:
Start where your data already lives. You may not need a new platform to get resolved identities.
Measure honestly. Know how you'll check whether matches are right before you start matching.
Use AI where it pays off. Quality checks, hard cases, and operations, not brute force, at least not yet, unless you've costed it out. Revisit this decision regularly as technology and pricing evolve.
Plan for what comes next. Golden records, CRM write-back, and real-time matching can follow once the foundation is in place.
Whether a vendor platform, a custom build, or a combination is right for you depends on your data, your team, and what you need resolved identities to do. Whichever route you choose, get this foundation right, and every report, campaign, and AI tool built starts from reliable data.
I can assure you a Clark never accidentally inserts an e in their name.
AWS,AWS Entity Resolution Pricing: $0.25 per 1,000 records processed for rule-based or machine-learning matching, so 2.4 million records cost about $600 per run. Machine-learning matching reprocesses the full dataset on every run; rule-based matching can process only new records after the first run.
Salesforce,Flex Credits Rate Card, June 17, 2026. Data 360 Unification (identity resolution) is billed at 75,000 credits per million rows processed at the base tier, compared with 3,500 for the Streaming Pipeline and 60 or fewer for Prep, Segmentation, Activation, and Queries.
Senzing,Pricing: $58,560 per year for 10 million data source records.
AWS Marketplace,Informatica Intelligent Data Management Cloud: $131,760 for a 12-month contract of 120 Informatica Processing Units per month. These units are consumed across Informatica's cloud services, including master data management.
Third-party estimates, not Informatica list prices, since Informatica doesn't publish them. Mammoth Analytics,Informatica Pricing (updated September 2026), puts MDM "enterprise pricing starting around $200,000/year." Automation Atlas,Informatica Pricing Explained (July 2026), estimates "~$200,000-500,000+/year" for a large enterprise running Informatica's full cloud platform with MDM.
AWS Marketplace,Reltio Data Cloud: $15,600 per month per unit, or about $187,000 over 12 months. The listing doesn't define what a unit covers.
Vendr, a software purchasing platform, reports that the median Reltio buyer pays about $393,000 per year.
Tamr's and Profisee's pricing pages offer quotes on request but list no prices.
Forrester Consulting,The Total Economic Impact™ Of The Semarchy Data Platform, commissioned by Semarchy, May 2025. The study models a composite organization with $10 billion in annual revenue, based on interviews with Semarchy customers. Implementation takes six people over six months plus a $25,000 fee, about $370,000 in total, and ongoing development, upgrades, and integration take two full-time staff, about $230,000 per year.
Based on the project's measured run times. The person and organization jobs run in parallel for about 20 minutes on one Snowflake container node billed at 0.336 credits per hour, roughly 0.2 credits in total, plus under two minutes of warehouse time for the SQL steps. At Snowflake's on-demand list price of $3 per credit (Enterprise edition, AWS US East), that comes to well under a dollar. Snowflake,Pricing Guide. Snowflake,Service Consumption Table (container node rate for the MEM_X64_G2_8 instance family).
List prices as of October 2026, per million input and output tokens: GPT-6.1 Sol, $2 and $10; Claude Opus 5.5, $4 and $20; Claude Sonnet 5.5, $2 and $10; Claude Haiku 5.5 (<100k tokens) and GPT-6 Luna at $0.10 and $0.50. Both vendors discount batch requests by 50%. A full pass costs about $3,400 one pair at a time or $730 batched with GPT Sol, and about $170 or $36 with GPT Luna. Claude's newer models also count about 30% more tokens for the same text, so they cost somewhat more in practice than their list prices suggest. The estimates assume about 240 input tokens and a one-word answer per pair when each pair is sent on its own (the prompt used for this project's AI review), and about 100 input tokens per pair when many pairs share one request. These figures assume the full prompt is sent with every pair, as happens when a model is called row by row through Snowflake's AI_COMPLETE function (other efficiencies could lower them). Anthropic,Pricing. OpenAI,API Pricing.
TypeSafe AI released Jev in September 2026. It is not a text-generating language model, but instead it returns a choice from a fixed list, a placement on a rubric, or the probability that a statement is true. DeepLearning.AI, The Batch, "Models Built to Do One Thing Well".
TypeSafe AI lists Jev at $0.042 per million input tokens ($42 per billion), with output free. This is less than half of what OpenAI's Luna would cost judging the same pairs one at a time. The estimate uses the same assumptions as the earlier comparison (about 240 input tokens per pair, sent one pair at a time), plus room for the question wording. One request can ask both "Same person?" as a probability and a plain match or no-match answer, so getting both adds little cost. Luna is cheaper when many pairs are packed into one batched request (about $36; see note 12), but Jev evaluates one pair per request. TypeSafe AI, Introducing System One Models and Jev. Note that even though there may be other efficiencies possible, for this we are assuming Snowflake's implementation via its AI_COMPLETE function or similar.
Snowflake offers these models as snowflake-decision through its AI_COMPLETE function, built on a Jev adapter during the preview. Its yes/no probabilities stay within roughly 0.08 to 0.92. Snowflake,Snowflake Decision with AI_COMPLETE (private preview).